 From strategy to launch, we design and build the products our clients grow on.See Case StudiesSee Case Studies
 Explore
- ServicesOur ServicesWhat We BuildMarketing sites & platformsCustom internal toolsAI features & automationDesign systems & rebrandsCampaign & content programsNot sure which team you need?Book a 30-minute discovery call with our product and engineering leads.


What AI Product Teams teams need most
WHAT WE BUILD
Data platforms & applied AI

Prompt & Retrieval Pipelines
Versioned prompts and retrieval settings that can be compared and rolled back.
Evaluation Sets
Real tasks with expected outcomes, rerun on every model or prompt change.
Guardrails & Fallbacks
Rules that withhold an answer and hand off when confidence is low.
Usage & Cost Tracking
Tokens, latency and spend attributed per feature and per customer.
Human Review Queues
Flagged outputs routed to a person with the source context attached.
Feedback Capture
Thumbs, edits and corrections collected as signals rather than as noise.
Where AI Product Teams teams lose time
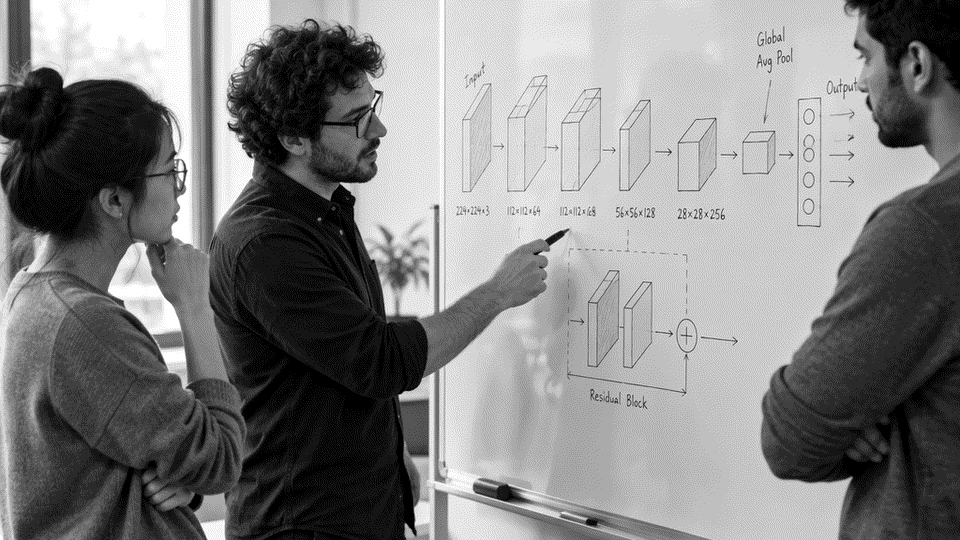
An AI product team ships a feature and then waits for complaints. The model is one part of the work. The rest is retrieval, prompt handling and a product surface that has to cope with odd input. Most teams cannot say whether last week's change made things better.
We build the measurement around the feature. A fixed set of real tasks runs against every change, guardrails decide when the system should refuse, and usage, cost and human review are visible together, so a release is a decision rather than a hope.
01
Demos as evidence
A change is approved because three examples look better in a demo, and nobody can compare it against the tasks users actually send.
02
Failures found by users
Problems surface in support tickets weeks after release, by which time two more changes have shipped on top of the one that caused them.
03
Cost discovered late
Token spend appears on the monthly bill, with no view of which feature, customer or prompt produced it, at a level anyone can act on.
HOW THE BUILD RUNS
OUR PROCESS
Step 01
Walk the workflow
We sit with the people who do the work and follow one job from first contact to final invoice. The gaps show up quickly once nobody is describing them from memory.
Step 02
Model the data
Bookings, orders, patients or jobs become one set of records with clear owners. We agree on the fields before any screen gets built.
Step 03
Build in stages
The costliest step ships first, usually the one where revenue or time leaks. Each stage goes live while the next one is being built.
Step 04
Hand over and support
Your team gets training, written runbooks and a support window. We stay close through the first month of real use, then step back.
SYSTEMS WE CONNECT TO
INTEGRATIONS
We build around what you already run. These are the systems we most often read from, write to, or replace one part of, without asking your team to start over.
Data warehouses and lakes
Identity and access systems
Help desk and CRM tools
Document storage
Monitoring and evaluation tools
THE TARGET
6-8 wk
Pilot to Production
Typical timeline for a scoped, evaluated AI pilot.
THE EXPERIENCE
100%
Evaluation Coverage
Every AI output path tested before release.
THE COVER
24/7
Guardrails
Monitoring, fallbacks, and cost controls running continuously.
THE HANDOVER
1
Source of Truth
A single governed warehouse behind reporting and AI.
OTHER SPECIALTIES
AI & Data Intelligence
QUESTIONS & ANSWERS
Questions about AI Product Teams
The questions that come up before a ai & data intelligence engagement starts.
How do we know the model got better?
By keeping a fixed evaluation set from real tasks and running every prompt, model or retrieval change against it. Without that, a demo is not evidence.
Should we build or buy the model layer?
Use a hosted model unless you have a specific reason not to. The durable work is retrieval, evaluation and the product around the model, not the weights.
How do you control cost?
By logging tokens, latency and outcome per request, then routing easy cases to cheaper paths. Cost work starts with visibility, not with a smaller model.
How large should an evaluation set be?
Start with the tasks your team argues about, often a few dozen, and grow it as failures appear. Coverage of the ugly cases matters more than raw size, and the set should include questions the product must refuse.
Can we test a new model before switching?
Yes. The same evaluation set runs against both versions, and the comparison is read task by task. A switch is then a decision with evidence, and rolling back is a setting rather than a rebuild.
How do guardrails affect the experience?
They trade a small amount of coverage for fewer confident errors. When the system withholds, it offers a fallback such as a source link or a handoff, so the user is not left at a dead end.
HOW WE HELP
The wider team behind this work
Most specialty builds draw on more than one service line. One team, one scope, no handoffs between vendors.


Talk to us about ai product teams.
Tell us what your team runs today and where it breaks. A real person replies, usually the same day.
Start a conversation
Start a conversation
contact us
Let's Talk About Your Project
Scope the problem and its constraints
Review your current product and stack
Agree on timeline, team, and budget
Cover security and compliance needs
Plan integrations with your tools
Leave with a clear first milestone
edgeless solutions

edgeless solutions
edgeless solutions
edgeless solutions
edgeless solutions